What is a blockchain indexer?

Written by Usman Asim
A blockchain indexer turns a chain of blocks into data an application can search. A node will return block 21,000,000. It will not, on its own, return every USDC transfer to one wallet, or every position a lending contract has opened. Those answers require someone to read the chain, decode the logs, and store the result.
Teams either run that pipeline or call a managed API that already did the work. Standard questions (token balances, transfer history, NFTs, prices) are usually a managed API. Custom questions (your own tables, your own events, SQL across protocol state) are usually an indexer you operate.
How blockchain indexers work is the same shape either way: extract blocks, transform them into records, and load those records where a query can find them. However, stored answers go wrong when the chain replaces a recent block and you keep the old rows, when the history is still unread, or when the job stops halfway through a write. In this guide: how the pipeline is built, what to do in each of those three cases, a runnable indexing loop, and when to build an indexer versus call a managed API.
What is a blockchain indexer?
A blockchain indexer is a service that reads new blocks from a node, decodes transactions and event logs, and writes them into a database built for lookups. Apps then query that database, or an API in front of it, instead of scanning the chain from the first block on every request.
Blockchains store blocks in order. That order is what consensus needs. It does not let you look up one wallet. There is no SELECT * FROM transfers WHERE to = ... on the node. The closest call on Ethereum is a method like eth_getLogs or eth_getBlockByNumber, which returns one block, or one range of logs. Finding "everything this address did" means repeating that call across the chain's history, then keeping the result yourself.
An indexer does that work ahead of time and saves the result. Wallet history, NFT ownership, DEX volume, and lending positions are calculated answers. The chain does not store them as a field you can read.
How do blockchain indexers work?
A blockchain indexer runs a loop: pull a range of blocks, decode the logs and transactions you care about, write rows, and save the last block you finished. The next run starts at the following block. You do not read the chain from the beginning again.
The loop has three stages.
- Extract. Read blocks, receipts, or logs from a node. To stay current, read each new block as it is added. To catch up on older blocks, read them in small ranges.
- Transform. Decode raw hex with a contract ABI. A topic hash becomes an event name. A
uint256in wei becomes a token amount. You can also store a timestamp or a price on the row. - Load. Insert the decoded rows into a database. Add an index on the columns you will search: address, contract, token id, block number. Serve those rows through an API.
That is the whole loop. The rest of this page is how to keep those rows correct when the chain replaces recent blocks, when years of history are still unread, and when the process crashes halfway through.
What is the architecture of a blockchain indexer?
Most indexers, whether you run them or a vendor does, are four pieces: a data source, an indexing engine, a database, and an API. The engine is the code that decodes logs, drops rows when the chain replaces a block, and reads older blocks in ranges. The database is what the app queries, so a search for one address does not read every row you stored.
Data source
The data source is the node's JSON-RPC or a provider endpoint in front of it. The indexer asks for new blocks, the transactions in those blocks, and the logs contracts emitted. Some indexers also read traces, which show value moved inside a transaction, not only the top-level call.
Indexing engine
The indexing engine decodes what the node returned and decides what to store. A raw log is a list of topic hashes plus a data field. The engine uses the contract ABI to turn that into a record you can read: a token transfer, a swap, a liquidated position.
It also keeps a current balance. A chain stores each change, not a ready-made answer to "what does this wallet hold right now?" Balances and ownership are the sum of every transfer so far. The engine keeps that sum as it goes, or stores the transfers and computes the sum when someone asks.
A database index on to_address is how you find one wallet's transfers without reading every row.
Database
The database holds the decoded rows. The questions you ask decide which kind to use:
- Relational databases such as PostgreSQL fit transfers, balances, and joins across blocks, addresses, and contracts.
- Document stores fit records whose fields change from one contract to the next.
- Graph databases fit questions about connections: which wallets sent tokens to which wallets, and which pools share liquidity.
- Warehouses such as BigQuery fit large scans and totals, not a query a user is waiting on while a page loads.
A common setup writes the same rows twice: once to the database the app reads, and once to a warehouse analysts query.
API
The API is what the app calls. GraphQL lets the client pick fields. REST fits known queries such as "transfers for this address." A websocket or webhook sends the app a new row when one is written, so the app does not have to keep asking.
Caching, rate limits, and API keys sit in this layer, so one client cannot overload the database.
How do indexers handle reorgs?
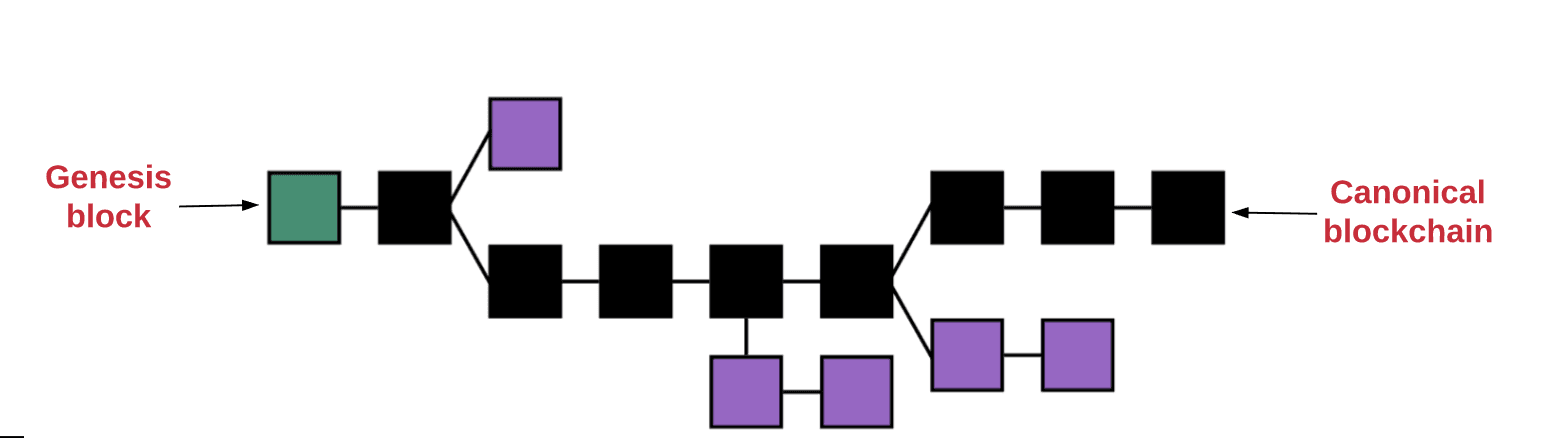
An indexer handles a reorg by noticing that a stored block is no longer the parent of the newest block, deleting the rows from the blocks that were replaced, and indexing the new blocks. Skip that step and the database still contains transactions the network did not keep.
A reorg happens when consensus replaces a short stretch of recent blocks, usually only a few. If you ignore it, a transfer you showed the user never landed, or a balance you saved is wrong.
A practical check on every new block:
- Read the new block header and its
parentHash. - Compare that hash to the hash you stored for the previous block.
- If they match, decode and insert.
- If they do not, walk backward until you find the common ancestor.
- Delete every row from blocks after that shared ancestor.
- Index forward from the ancestor along the blocks the network kept.
Logs can also arrive with removed: true. Treat that flag as a delete, not as another insert. Give each row a unique key the chain already provides, such as (chain_id, transaction_hash, log_index), so writing the same log again does not count it twice.
If your product can wait, index only blocks the node marks as finalized or safe. Those are past the point where a replacement is still likely. You wait a little longer, and you rarely have to delete rows. A block tagged latest can still be replaced, so an indexer that follows the newest block cannot treat it as permanent.
How does a backfill work?
A backfill is the first read of older blocks. The indexer walks from a start block to the newest block in fixed ranges, writes rows, and saves the last finished block. A restart continues from that block instead of starting over at block zero.
History on Ethereum is tens of millions of blocks. One request cannot hold that. eth_getLogs is the usual tool, and the range you may ask for depends on the plan and the chain. On the free tier, a single call is limited to 10 blocks. On Ethereum, Base, Optimism, Arbitrum, Polygon, and the other chains in the first row of the eth_getLogs reference, pay-as-you-go and Enterprise have no block-range cap. Every response, on every plan, is still capped at 150MB. On most other chains, pay as you go allows 10,000 blocks per call. Monad testnet and Berachain are lower. The table lists each chain. Split anything larger. A response that hits the byte cap fails the same way an oversized range does.
A backfill that survives failure looks like this:
- Store a cursor: the last block you fully committed.
- Request the next range, sized under the cap for that chain and plan.
- Decode, then commit rows and the new cursor in one transaction.
- Repeat until the saved block reaches the newest block.
- Switch from reading old ranges to following new blocks.
Save the cursor only after the rows for that range are saved. If you advance the cursor first and then crash, those blocks are skipped forever. If you write the rows first and then crash before the cursor moves, the next run repeats them, which is safe if the same log cannot be inserted twice.
Parallel backfills split the range across workers. They still need one ordered save, or a merge step, so two workers do not write different versions of the same block.
How do you recover an indexer?
Recovery means starting again from the last saved block that is still on the chain the network kept, then reading forward to the newest block. You use the same code as the backfill, on a shorter stretch of blocks.
When a process comes back after downtime, do not assume the saved block is still valid:
- Load the stored block number and block hash.
- Fetch that block from the node again.
- If the hash still matches, the saved block is still the one the network kept. Resume from the next block.
- If the hash does not match, the chain replaced blocks while you were down. Walk back through parent blocks until the stored hash matches, roll the database back to that block, and resume.
- Read forward until you reach the newest block. Do not skip the missing blocks to catch up faster. Those blocks are the transfers you lost.
The failure to avoid is a gap: block 18,000,000 saved, block 18,000,500 saved, and nothing in between. Users will not see the gap. They will see a missing transfer and a wrong balance.
Two habits make recovery routine. A unique key makes it safe to write the same block again. Saving the cursor in the same database transaction as the rows means a crash stops at a block boundary, not halfway through a block.
What does an indexing loop look like in code?
The loop below is a real eth_getLogs backfill against Ethereum. It reads the newest block, walks a 10-block window (the free-tier maximum), and prints each USDC Transfer log. Save it as a .js file, set ALCHEMY_API_KEY, and run it with Node 18 or newer.
const url =
"https://eth-mainnet.g.alchemy.com/v2/" + process.env.ALCHEMY_API_KEY;

// keccak256("Transfer(address,address,uint256)")
const TRANSFER_TOPIC =
"0xddf252ad1be2c89b69c2b068fc378daa952ba7f163c4a11628f55a4df523b3ef";
const USDC = "0xA0b86991c6218b36c1d19D4a2e9Eb0cE3606eB48";

// Free tier: 10 blocks per eth_getLogs call. Widen this only on a plan
// whose range cap allows it. Responses are capped at 150MB on every plan.
const RANGE = 10;

async function rpc(method, params) {
const response = await fetch(url, {
  method: "POST",
  headers: { "Content-Type": "application/json" },
  body: JSON.stringify({ jsonrpc: "2.0", id: 1, method, params }),
});
const body = await response.json();
if (body.error) {
  throw new Error(JSON.stringify(body.error));
}
return body.result;
}

async function backfill(fromBlock, toBlock) {
let cursor = fromBlock;
while (cursor <= toBlock) {
  const end = Math.min(cursor + RANGE - 1, toBlock);
  const logs = await rpc("eth_getLogs", [
    {
      fromBlock: "0x" + cursor.toString(16),
      toBlock: "0x" + end.toString(16),
      address: USDC,
      topics: [TRANSFER_TOPIC],
    },
  ]);

  for (const log of logs) {
    // removed: true means the log was on a block that got reorged out.
    if (log.removed) continue;
    const key = log.transactionHash + ":" + log.logIndex;
    console.log(key, log.blockNumber);
  }

  // In a real indexer, commit rows and this cursor in one transaction.
  cursor = end + 1;
}
}

async function main() {
const head = Number(await rpc("eth_blockNumber", []));
await backfill(head - (RANGE - 1), head);
}

main();
A production version writes those logs into a table with a unique key on (transaction_hash, log_index), stores the cursor beside them, and runs the parent-hash check from the reorg section before it treats the newest block as final. Decoding topics[1] and topics[2] gives the indexed from and to addresses. The amount sits in data.
For one address's history, you usually should not run this loop at all. alchemy_getAssetTransfers returns that history a page at a time. Send a returned pageKey on the next call until the response leaves it out. Each call costs 120 compute units. eth_getLogs costs 60, and you still have to page, decode, and store.
async function main() {
const url =
  "https://eth-mainnet.g.alchemy.com/v2/" + process.env.ALCHEMY_API_KEY;

const response = await fetch(url, {
  method: "POST",
  headers: { "Content-Type": "application/json" },
  body: JSON.stringify({
    jsonrpc: "2.0",
    id: 1,
    method: "alchemy_getAssetTransfers",
    params: [
      {
        fromBlock: "0x0",
        toAddress: "0x5c43B1eD97e52d009611D89b74fA829FE4ac56b1",
        category: ["external", "erc20", "erc721", "erc1155"],
        withMetadata: true,
        excludeZeroValue: true,
        order: "desc",
        maxCount: "0x64",
      },
    ],
  }),
});

const body = await response.json();
// If body.result.pageKey is set, call again with that pageKey until it is absent.
console.log(body.result.transfers);
}

main();
category is required. Values are external, internal, erc20, erc721, erc1155, and specialnft. Internal transfers are available on Ethereum mainnet, Polygon mainnet, Base mainnet, Arc mainnet, and Arc testnet. withMetadata: true adds a block timestamp, on Ethereum, Base, Polygon, Arbitrum, and Optimism. Results page at 1,000 rows. Send a returned pageKey on the next call until the response leaves it out. That key expires after 10 minutes. order: "desc" returns newest first. order: "asc" returns oldest first.
During a fork or a partial outage, toBlock: "indexed" reads from the indexed cache instead of the newest block. That result can sit a few blocks behind. Use it when a slightly older history is better than an error.
Should you build an indexer or use a managed API?
Use a managed API for balances, transfers, NFTs, and prices. Build an indexer when you need your own tables: custom events, positions, reserves, or a SQL query no shared endpoint returns.
The Data APIs are the managed path for the common reads. Transfers API returns historical transfers for an address in pages of up to 1,000, including external, ERC-20, ERC-721, and ERC-1155 transfers, instead of scanning the chain. Send a returned pageKey on the next call until the response leaves it out. Token API returns metadata and balances. NFT API returns ownership. Prices API returns current and historical prices. Portfolio API combines tokens, NFTs, and transfers, including a multichain transfers-by-wallet method.
Custom Webhooks are the managed path for live custom events. You filter with GraphQL and receive an HTTP callback for the latest block the network currently accepts. They are not a historical store. For history, use the Transfers API. Each callback includes a sequenceNumber, an incrementing integer you can use to notice a replaced block. A gap or a step backward in that sequence means you should fetch those blocks again. An empty topic filter matches every event for the address and can get expensive. Set topics when you know the event.
Build when none of those endpoints returns the record your product needs. A lending protocol's health factor, an AMM's reserves after every swap, a points program based on your own event: you compute and store that yourself. A subgraph is a packaged indexer for that job. The Graph is the decentralized protocol: you publish a subgraph, and indexers serve it over GraphQL. Goldsky hosts subgraphs and streams decoded data into your own database. Alchemy Subgraphs was sunset on December 8, 2025. The deprecation notice points existing subgraphs at Goldsky.
If you are building the indexer, and eth_getLogs on the shared fleet cannot cover the range, use a dedicated cluster. The shared range cap exists so one customer cannot crowd out the others. A cluster that serves only you can raise that cap. You still have to handle replaced blocks, save your cursor, and run the database.
Frequently asked questions
What is a blockchain indexer?
A blockchain indexer reads blocks from a node, decodes transactions and event logs, and stores them in a database built for search. Applications query that database instead of scanning the chain from the start for every request. The node is still where the chain data comes from.
How does a blockchain indexer work?
It reads a range of blocks or logs, decodes the raw hex into records with a contract ABI, and writes those records into a database. A saved block number marks the last block you finished, so the next run continues from there instead of starting over.
Should I build an indexer or use a managed API?
Use a managed Data API for balances, transfer history, NFTs, and prices. Use Custom Webhooks when you need a push for a specific contract event. Build an indexer, or use a subgraph host, when you need your own tables and no shared endpoint returns them.
How do indexers handle reorgs?
They compare each new block's parent hash with the hash they stored. On a mismatch, they walk back to the common ancestor, delete rows from the replaced blocks, and index the new blocks the network kept. A unique key on each log keeps a second write from inserting it twice.
What is an indexer backfill?
A backfill reads older blocks in ranges, writing decoded rows and a cursor as it goes. The cursor moves only after those rows are saved, so a crash resumes at a finished block instead of leaving a gap or starting over at block zero.
How do you recover an indexer after downtime?
Reload the stored block hash, confirm it still matches the node, and resume from the next block. If the hash does not match, roll back to the last block the network kept and read forward again. Do not skip the blocks you missed. A unique key on each log makes it safe to write those blocks again.
What is the difference between an indexer and a full node?
A full node holds the chain and answers low-level reads such as "give me this block." An indexer stores a calculated answer, such as "give me this address's transfers," and reads it from a database. Most apps need both: the node for chain data, the indexer for search.
Does Alchemy host custom subgraphs?
No. Alchemy Subgraphs was sunset on December 8, 2025, and those query endpoints are discontinued. Custom subgraphs can move to Goldsky. For standard reads, the Data APIs still serve indexed transfers, tokens, NFTs, prices, and portfolios without hosting a subgraph.
Related Overviews
 Ethereum
June 21, 2022
What is a reorg?
What it Is, How They're Caused, and What Happens Next
 Infra
September 26, 2023
What is a subgraph? (Guide)
Learn How Subgraphs Work, How They Can Be Used, and How to Start Building
 Infra
June 15, 2026
How dedicated blockchain infrastructure works
Dedicated blockchain infrastructure puts RPC and indexing workloads on single-tenant clusters. Here's how isolation, regions, redundancy, and failover work.
Build blockchain magic
Alchemy combines the most powerful web3 developer products and tools with resources, community and legendary support.